Tag: Content operations

  • We wrote a second checker for the space between articles. It caught two orphans on day one.

    We wrote a second checker for the space between articles. It caught two orphans on day one.

    Every automated check we had looked inside a single article. Links resolve, disclosures are present, no duplicate of anything published before. Nine checks, all of them scoped to one piece of writing at a time.

    Our three worst failures were all outside that scope. A sitemap frozen for ninety-three days. An article that went twenty-seven days without a crawl. A site with no internal links at all. Each individual article was fine. The site was not.

    So we wrote a second checker, at a different scale. This is what it looks at, what it found immediately, and where it runs.
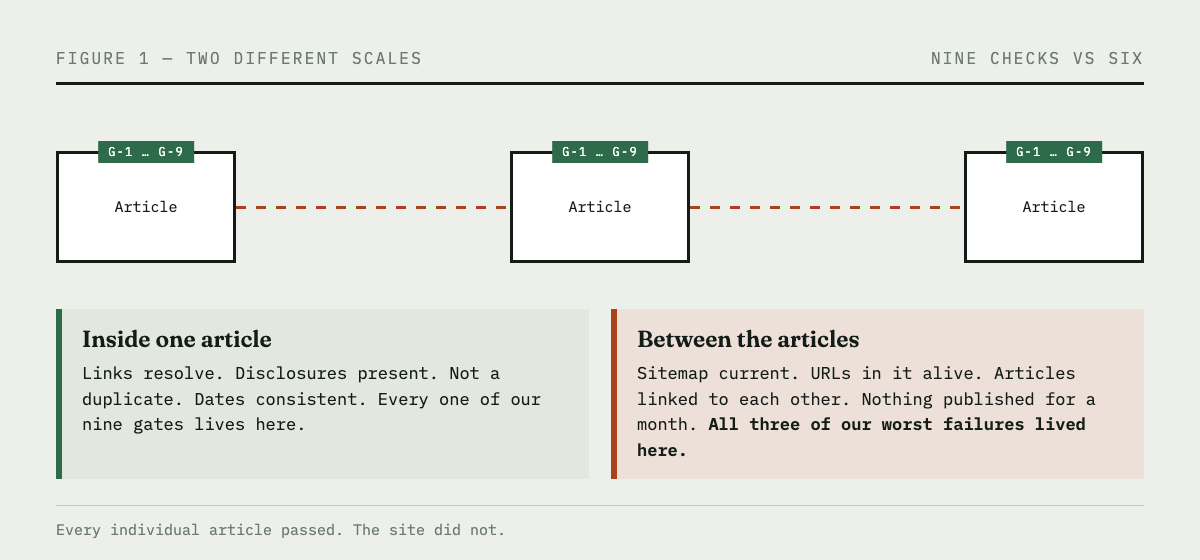
    A diagram of three article boxes. The nine per-article gates wrap each box. The dashed lines running between the boxes mark the space where our worst failures lived.
    Nine checks guard each box. Nothing was watching the dashed lines.

    The six checks and where each one came from

    None of these are clever. Each exists because we lived through the thing it now catches.

    Is the sitemap current? Ours had been frozen since June. It was still advertising eleven pages we had deleted while listing none of the ones we had published since.

    Do the URLs in the sitemap resolve? Those eleven returned 404 to anything that followed them.

    How many article-to-article links exist? Across our English site the answer was six. On the Japanese site it was two, and both of those were between the same pair of posts.

    Which articles have nothing pointing at them? These are dead ends for a crawler. A reader who lands there has nowhere to go except back.

    Which articles point at nothing? The same problem from the other side.

    How old is the newest article? A site that has not published in a month is a different kind of broken, and nothing reports it.

    Six checks, a few hundred lines, standard library only. Writing it took about an hour, most of which was spent on the link graph.

    What it found

    The Japanese site had four articles with no article-to-article links in either direction. They had been that way since publication. All four were still linking correctly to legal pages, which is why a visual check had passed them for months — the links were there, they just went nowhere useful.
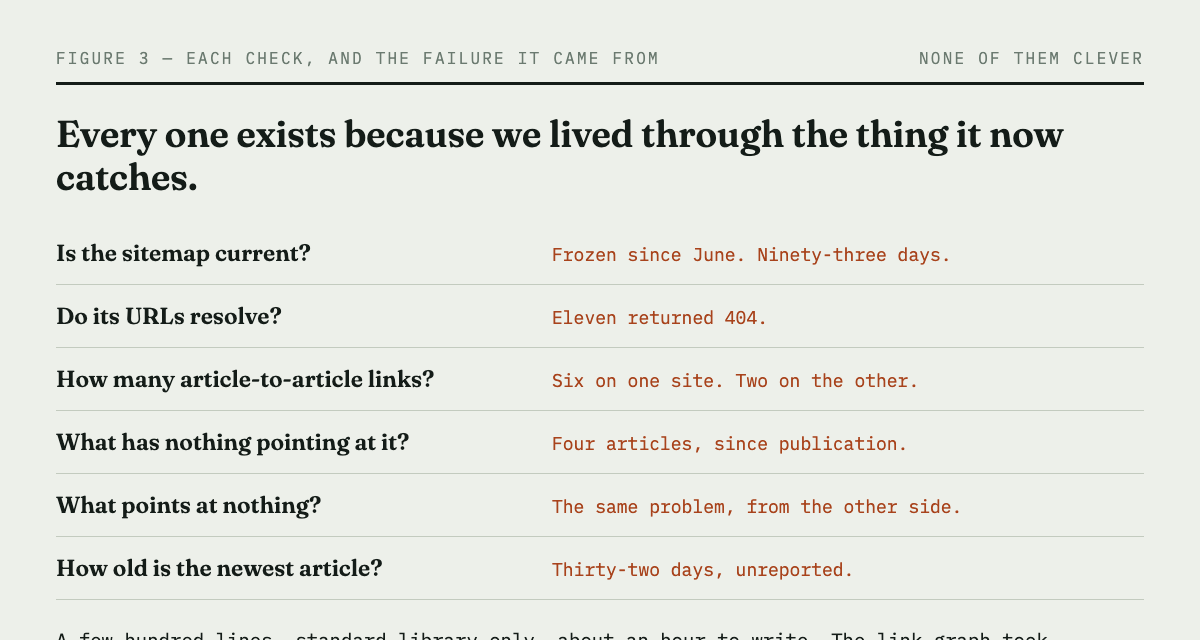
    Six site-level checks listed against the real failure each one came from. A sitemap frozen ninety-three days. Eleven URLs returning 404. Six article-to-article links. Four articles with nothing pointing at them. A newest article thirty-two days old.
    A checklist built from scars again, which is the only way these ever get written.

    Then it caught something while we were still working.

    We publish through a script. That script now runs the site checker immediately after a successful publish. On the first article we shipped after building it, the output read:

    Gates passed, article published, then a failure line: one article with nothing pointing at it. The article it was complaining about was the one we had just published, forty seconds earlier.

    We fixed it before the page had been crawled. The same thing happened again a few hours later with an article on the Japanese site. Two catches on the first day, both of which would otherwise have sat there until somebody noticed.
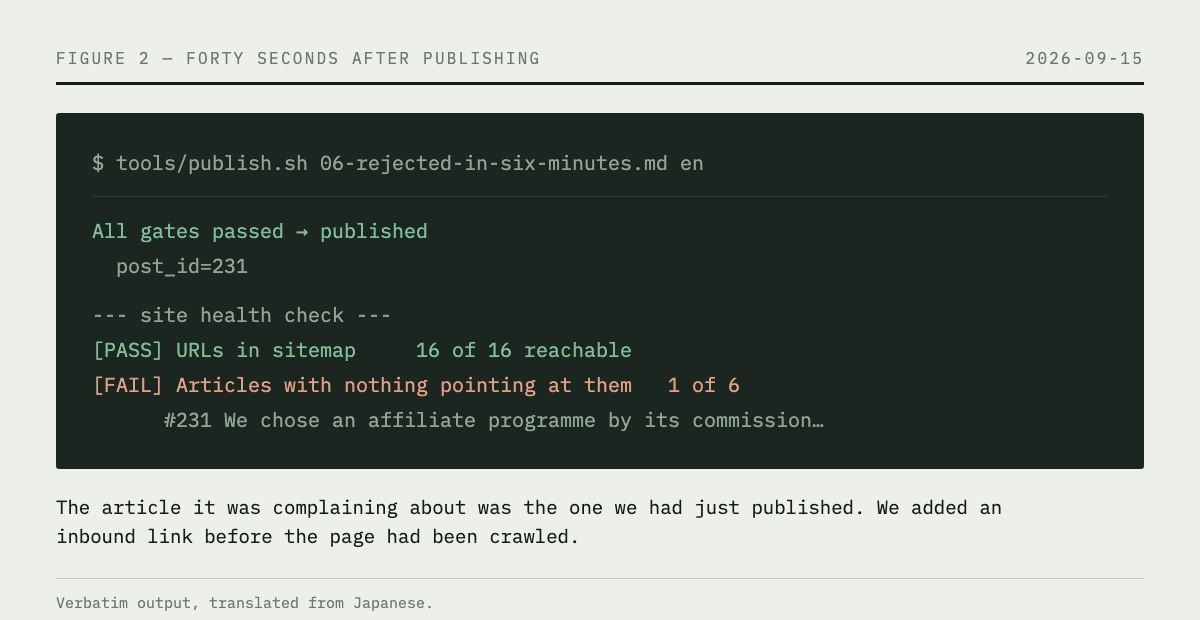
    Terminal output showing an article publishing successfully, then the site health check immediately reporting one article with nothing pointing at it. The article it flagged was the one just published.
    The first article we shipped after building it. The check was complaining about that very article.

    Where it runs

    Two places, for two different reasons.

    Immediately after every publish. A new article starts life with nothing pointing at it. That is the default state, not an unusual one, so the moment of publishing is exactly when the check is worth running. The site check does not block the publish and cannot undo it — the article is already live, and the check is telling you what to do next.

    Every morning at nine. Rot is not an event. The sitemap did not break on a particular Tuesday; it stopped updating and then stayed stopped for three months. Only a repeated check finds that kind of failure.

    The part that decides whether any of this works

    The checker writes a dated report to a folder. If that were the whole design, it would be worthless.

    A report nobody opens is not monitoring. It is a second copy of the original problem, because the entire failure mode we are trying to fix is information that existed and was never read. The sitemap was visible in a browser the whole time. Search Console would have answered the crawl question for anyone who asked it. Nobody asked.

    So the check raises a system notification when something fails. That notification is the actual product; the report is just where the detail lives.

    We verified that the notification appears. This sounds like an unnecessary step until you remember that the command to display one returns success whether or not the operating system shows anything, which is the same shape as a publishing API that returns 201 for an article that reaches readers as raw markup. An exit code describes the call. It does not describe what a person saw.

    What it cannot do

    It does not know whether an internal link is any good. A link exists or it does not; whether it was worth placing where it sits is a judgment. Nothing here stops you from satisfying every check with a block of related links at the bottom of each article, which passes the counter while helping nobody.

    It also has no opinion about whether the articles are worth reading. That was true of the per-article gates as well. Both checkers clear the floor so the attention goes somewhere that needs it.

    If your site is small

    You can run the first three checks by hand in under two minutes, today, without writing anything.

    Open your sitemap in a browser. Look at the date on it, then click two or three of the URLs inside.

    Take your newest article and inspect its URL in Search Console. Not the ranking. Whether it has been crawled at all.

    Open any article and try to reach a different one by clicking. If you cannot, a crawler cannot either.

    If all three pass, you do not need a checker yet. If any of them fails, you have learned something more useful than a month of traffic data would have told you.


    Editorial note. Written and edited by the operator of this site. The counts, the dates, and the day-one results are from our own two sites and our own tooling, recorded on 2026-09-15.

    Disclosure. This article contains no affiliate or sponsored links. This site may earn commissions from links in other articles, and those articles carry their own disclosure at the top. Nothing here is professional advice.
  • We chose an affiliate programme by its commission rate. The rejection arrived in six minutes.

    We chose an affiliate programme by its commission rate. The rejection arrived in six minutes.

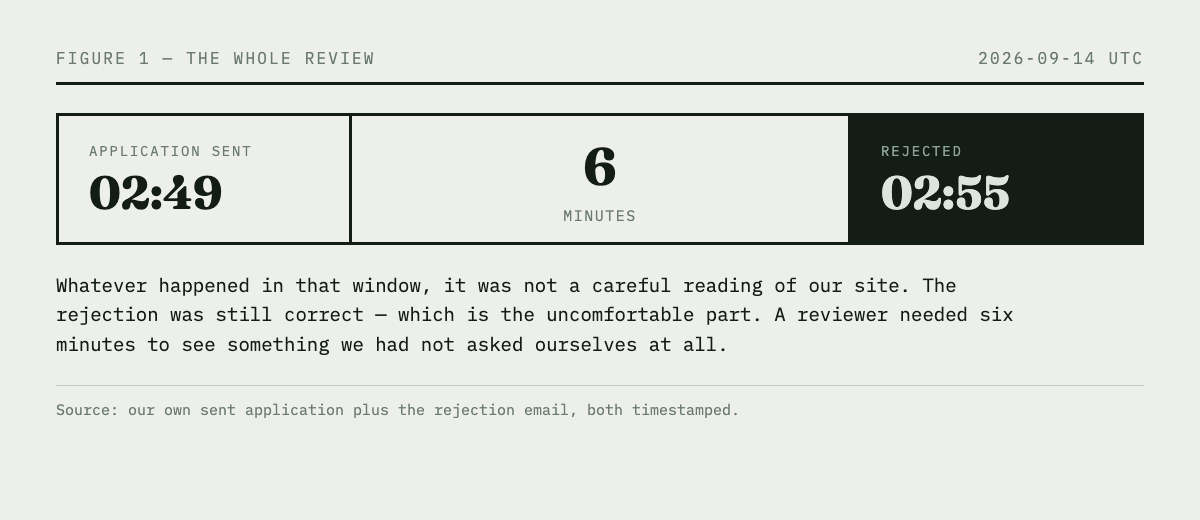
    We applied to an affiliate programme at 02:49 and were turned down at 02:55. Six minutes. Whatever happened in that window, it was not a careful reading of our site.

    The rejection was the right outcome. What is worth writing down is that we had picked the programme for a reason that could not survive contact with the question the reviewer was actually asking.

    A timeline showing the application sent at 02:49 and the rejection received at 02:55, six minutes later.
    The entire review, start to finish. The verdict was still right.

    How we chose

    We were looking for recurring commission, because a payout that resets every month means the work never accumulates. We had already done that arithmetic on our own numbers and concluded the volume model was unreachable for a site our size.

    So we ranked the candidates by commission rate and duration, picked the highest, and applied.

    That is the whole selection process. Written down like that, the gap is obvious. We never asked whether their customers were our readers.

    What the rejection said

    The email listed four possible reasons, in the generic way these templates do. Only one of them mattered:

    Your audience focuses on a different niche than ours — we partner with creators who help other creators earn a living online

    That is the programme describing its own customer in one sentence. Our articles are about publication gates, firewalls blocking their own owner, and instruments that were never connected. Our readers run small publishing operations. Those are adjacent worlds that share almost no purchase intent.

    No amount of rewriting the application would close that gap. We were the wrong applicant, and a better-written application would only have made us a more convincing wrong applicant.

    The part that was our fault

    One of the other four reasons did apply, and it was ours:

    Your application didn’t include enough detail about how you’d promote

    The first draft of our application described how we would promote the product in concrete terms. Then we shortened it, and the specifics were what got cut. What survived was a statement of editorial policy with no plan attached.

    Shortening was the right instinct. Choosing which parts to cut is a separate decision, and we made it badly.

    The arithmetic nobody does before applying

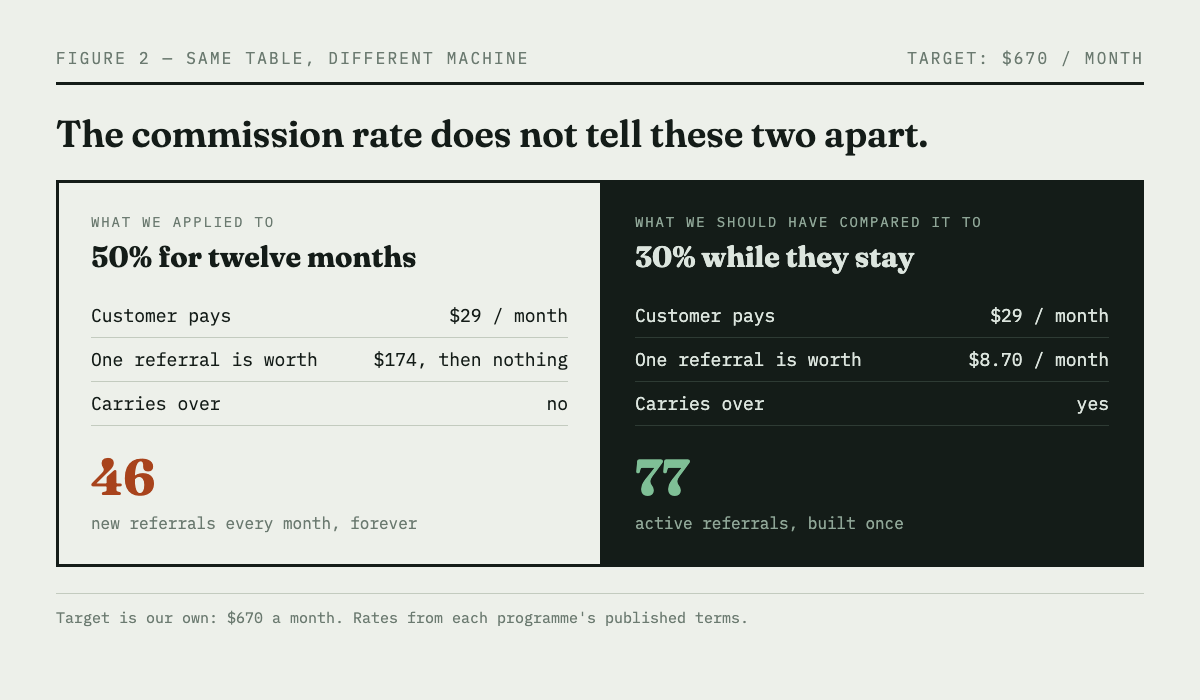
    Here is what we should have computed first. The programme paid 50% for twelve months, then a reduced rate only if you keep referring ten or more customers a year.

    Their customers pay roughly $29 a month. So one referral is worth about $174, spread over a year, and then it stops.

    To reach a modest monthly target from that programme alone, we would have needed about 46 new referrals every month, forever, because nothing carries over. Compare that with a programme paying 30% for as long as the customer stays: the same target needs a base of active referrals that you build once and keep.

    Two commission models side by side at the same customer price. The programme paying 50 percent for twelve months requires 46 new referrals every month. The programme paying 30 percent for as long as the customer stays requires a base of 77 active referrals built once.
    Two programmes that sit next to each other in any comparison table, doing completely different work.

    One of those is a treadmill. The other is a staircase. They look similar in a comparison table, and the commission rate is not what tells them apart.

    What we changed

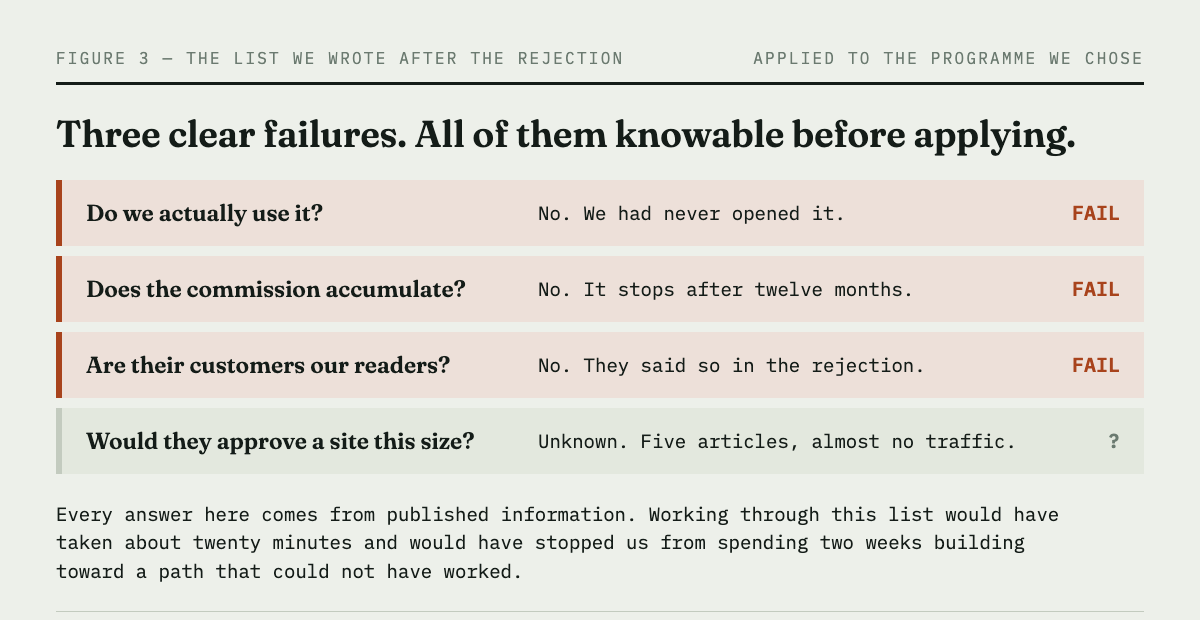
    We wrote down selection criteria before looking at any more programmes. Four of them, in order.

    Do we actually use it? We published a policy that we do not write about products we have not used. Applying to a programme for a product we had never opened meant that approval would have left us unable to write anything. We had put the steps in the wrong order.

    Does the commission accumulate? A rate that ends after twelve months is a one-time payout wearing a subscription costume.

    Are their customers our readers? Not adjacent. The same people, with the same problem, at the same moment.

    Would they approve a site this size? Five articles and almost no traffic is a real constraint, and pretending otherwise wastes everyone’s time.

    Four selection criteria applied to the programme we chose. Three are clear failures: we had never used the product, the commission stops after twelve months, their customers are not our readers.
    Scored after the fact. Every answer was available before we applied.

    Applying that list to the programme we had chosen, it fails three of four. We could have known that before applying, from published information, in about twenty minutes.

    If you are monetising a small site

    The commission rate is the most visible number and the least useful one. It is the last thing to compare, after you have established that the product is something you use, that the payment continues, and that the audience is genuinely the same.

    There is also a quieter cost to getting this wrong that has nothing to do with the rejection. We spent two weeks building toward a monetisation path that could not have worked, and none of that showed up as a failure until an automated email arrived six minutes after we asked. Most wrong turns in a small business are like that: they do not announce themselves, and the first real signal is much later than the decision.


    Editorial note. Written and edited by the operator of this site. The timestamps, the quoted lines, and the figures come from our own application and the rejection email we received on 2026-09-14. We have not named the individual who replied.

    Disclosure. This article contains no affiliate or sponsored links. We were not accepted into the programme discussed. This site may earn commissions from links in other articles, and those articles carry their own disclosure at the top. Nothing here is professional advice.
  • Eight automated checks passed. The reader saw asterisks.

    Eight automated checks passed. The reader saw asterisks.

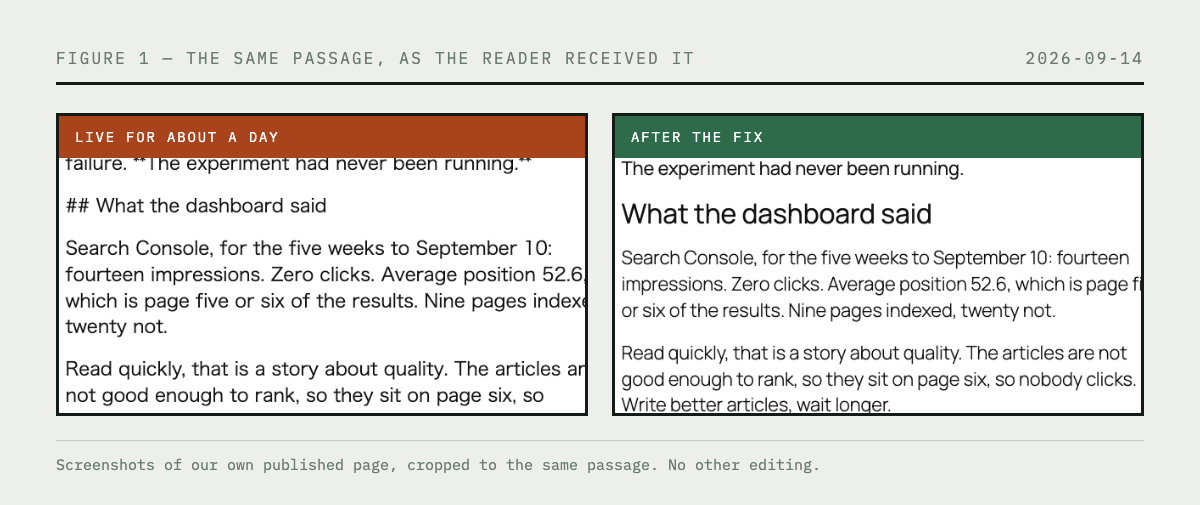
    For about a day, three of the four articles on this site displayed their own markup. Headings arrived as ## What the dashboard said, with the hashes sitting in the text. Bold arrived wrapped in asterisks. Links arrived as square brackets followed by a naked URL in parentheses.

    Every one of those articles had passed an eight-gate publication checker with no failures. The checker was working exactly as designed. That is the part worth writing down.

    What the reader actually got

    The left panel is a live article as published. The right is the same passage after the fix.

    Two screenshots of the same passage from our own published article. On the left, as it was live for about a day, the heading appears as hash characters and the bold text is wrapped in asterisks. On the right, after the fix, the heading renders as a heading.
    Our own published page, before the fix on the left. The reader met the markup before they met the sentence.

    How it happened

    Our publishing pipeline reads a file, runs the gates, then posts the body to the WordPress REST API. The articles were written in Markdown. WordPress does not render Markdown. It stores what you send it.

    The assumption was sitting in our own source code, in a comment on the data model:

    body: HTML or Markdown

    Nobody had ever tested the second half of that sentence. The first article on this site happened to be written in raw HTML, so it rendered correctly. When we switched to writing in Markdown, everything after it broke, quietly, in a way that looked fine from every angle we were checking.

    Why the checker did not catch it

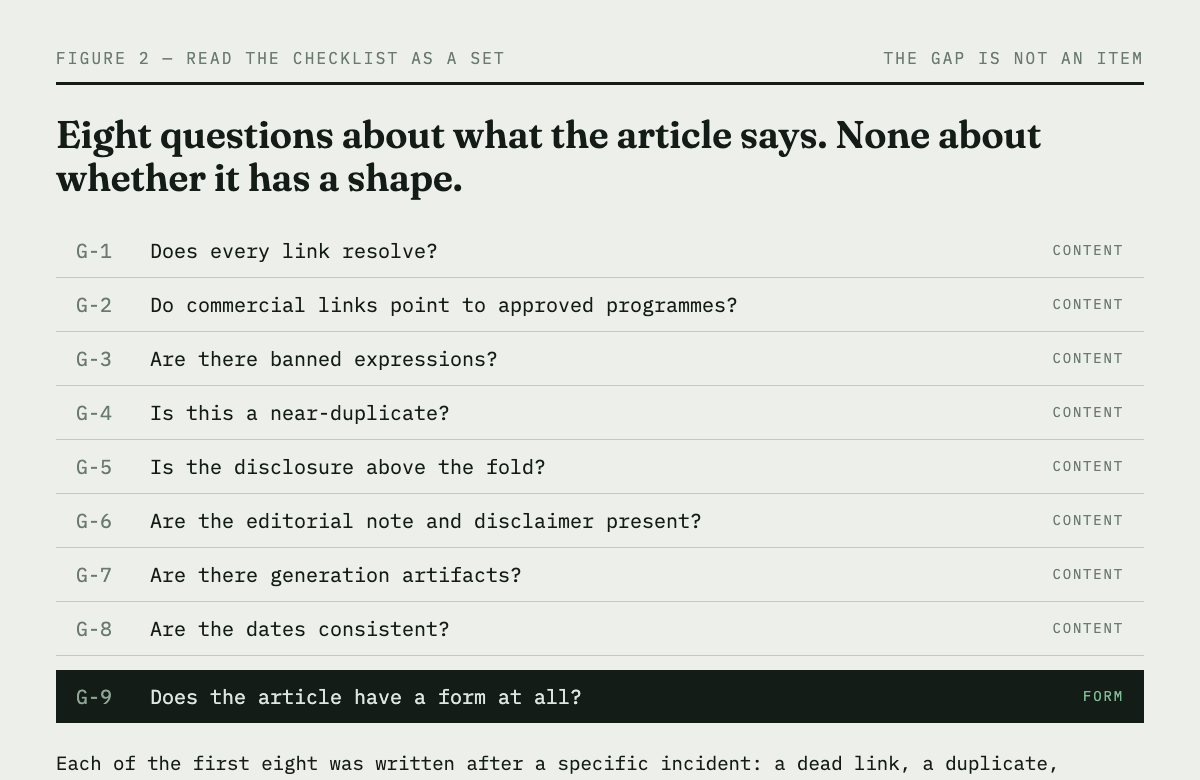
    This is the useful part. Here is what the eight gates ask:

    Does every link resolve? Do commercial links point only to approved programmes? Are there banned expressions? Is this a near-duplicate of something already published? Is the disclosure above the fold? Are the editorial note and disclaimer present? Are there generation artifacts in the text? Are the dates internally consistent?

    Read those eight as a set. Every single one is a question about what the article says. Not one of them is a question about whether the article has a form.

    The nine questions our publication gates ask. The first eight are all questions about what the article says. Only the ninth asks whether the article has a rendered form.
    Written out as a set, the shape of the blind spot is obvious. Added one at a time after incidents, it never was.

    That was not an oversight in the sense of forgetting an item. Each gate was written in response to a specific failure we had already lived through: a dead link, a duplicate, an income claim in a headline. The list was a list of scars. You cannot write a scar for an injury you have not had yet, which is precisely why a checklist built from experience has a predictable shape: it is dense where you have been hurt and empty everywhere else.

    The gap was not in the list. It was in the space the list did not cover.

    Why a human did not catch it either

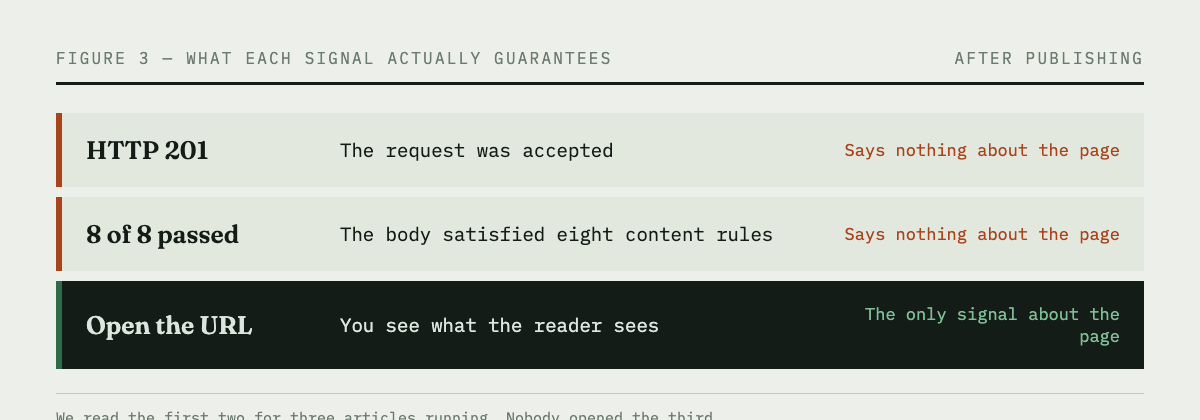
    We publish, then read the result of the publish. The API returned 201. The gate report printed eight passes. A person read both of those and moved on.

    Both of those signals were true. Both of them were about the system. Neither of them was about the page.

    Nobody opened the public URL. Not once, across three articles. The information was one click away for a day and a half, sitting in a browser tab nobody opened, because the dashboard had already said the thing was fine.

    This is the same failure we wrote about two weeks ago, where a site produced no revenue for fifteen months while the instrument measuring it was disconnected. Same shape. We read the report instead of the thing the report described. Knowing about the pattern in the abstract did nothing to stop us repeating it eleven days later.

    Three signals after publishing. An HTTP 201 means the request was accepted. Eight of eight passed means the body satisfied eight content rules. Only opening the public URL tells you what the reader sees.
    Two of these three signals were green for three articles running. Neither was about the page.

    What we changed

    A converter, so the input is always valid output. Markdown now becomes HTML before it reaches the API. A few hundred lines, standard library only, handling exactly the notation our articles actually use and nothing else.

    A ninth gate that fails closed. G-9 scans the body that is about to be posted for surviving markup notation. If it finds any, nothing publishes. Writing the gate took twenty minutes. It exists now because the failure happened, which is the same way the other eight got here.

    A second checker, at a different scale. The nine gates all look inside one article. We later built a set of checks for the space between articles, which is where our worst failures had been living.

    A rule that is not automated at all. After publishing, open the public URL and look at the page. Not the API response. Not the gate report. The page, as a reader loads it.

    That last one is the only part of this that generalises. The first two fix this specific bug. A machine check can confirm that a page contains no leftover asterisks. It cannot tell you that a paragraph is confusing, that a figure landed in the wrong place, or that the article now opens with two identical headlines because the cover image repeats the title. Every one of those was also true of our pages this week, and the only thing that found them was a person looking at the page.

    If you publish through an API

    Three things, in order of how much time they save.

    Load the public URL after every publish. The response code tells you the request succeeded. It tells you nothing about what the reader gets.

    Assume every comment in your own code is untested. The word or in a code comment is where bugs live. Ours said Markdown would work. It had never worked. It had simply never been tried, and the comment made it look like a decision rather than an assumption.

    When you add a check, ask what category it belongs to. Our eight gates were all one category. That is invisible while you are adding them one at a time in response to incidents, and obvious the moment you write them out as a list and read them together. If every check you have asks the same kind of question, you have a blind spot the exact size of the questions you are not asking.

    None of this made the articles better. It made them legible, which is the floor rather than the ceiling. But a reader who sees asterisks in the second paragraph does not reach the argument, so the floor is where the work has to start.


    Editorial note. Written and edited by the operator of this site. The screenshots are of our own pages, taken before and after the fix on 2026-09-14. The affected articles were live in the broken state for roughly one day.

    Disclosure. This article contains no affiliate or sponsored links. This site may earn commissions from links in other articles, and those articles carry their own disclosure at the top. Nothing here is professional advice.
  • We built an 8-gate checker for AI-drafted articles. The first run failed our own live site.

    We built an 8-gate checker for AI-drafted articles. The first run failed our own live site.

    Google’s guidance on scaled content abuse draws the line in a place a lot of people misread. It is not about whether a machine wrote the draft. It is about whether a person actually exercised judgment before it went live. That distinction sounds reassuring until you try to prove it. What does “a person reviewed this” look like six months later, when the only evidence is that someone remembers skimming it?

    We run a small publisher where the drafts are machine-written and the decisions are not. We have written before about what breaks when you hand the work to agents, and this is the control we built afterward. In September we stopped relying on memory and built a checker: eight gates, every article, fail-closed. Nothing publishes unless all eight pass.

    Then we pointed it at our own live site, which had seven published articles on it. It failed six of them.

    What the eight gates check

    The gates are deliberately boring. Each one exists because something specific went wrong, either to us or to someone whose postmortem we read.

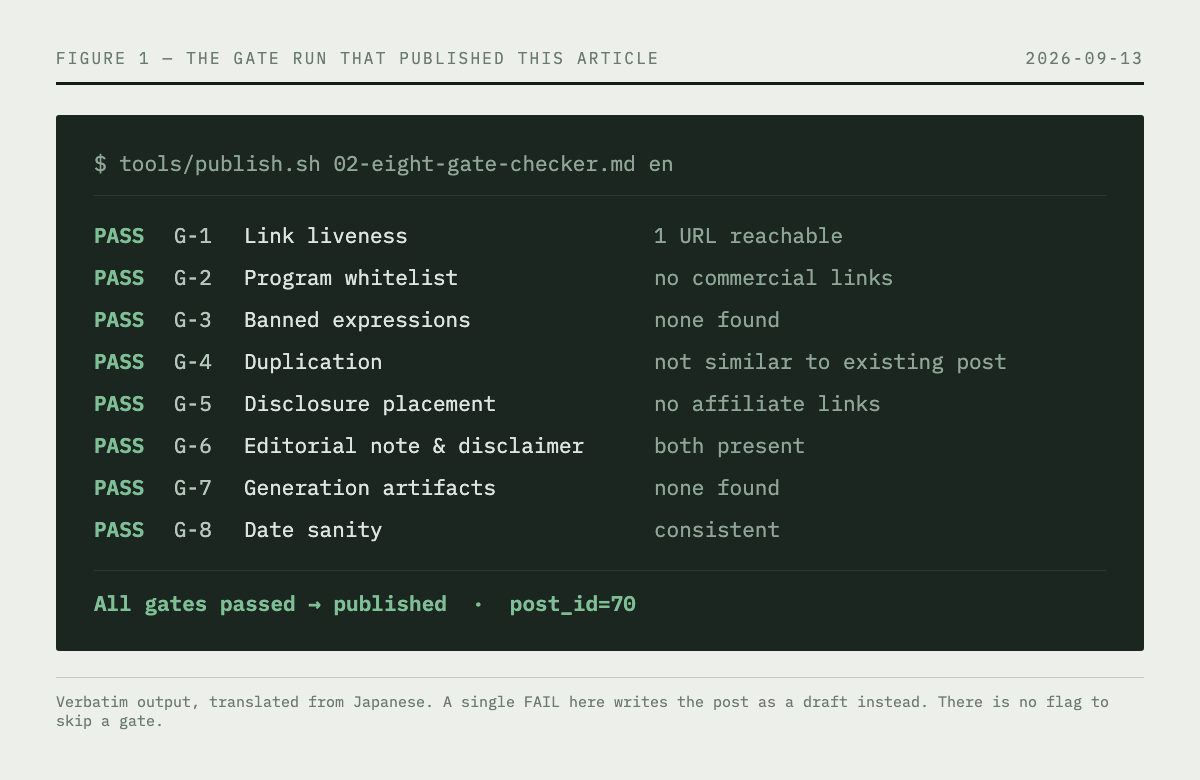
    G-1: every outbound link resolves. A HEAD request to each URL in the body. Link rot is slow and invisible, and a dead link in a comparison article is the reader’s last impression of you.

    G-2: every commercial link points to an approved program. The article can only link to advertisers we have an actual approved relationship with. On our English site, where we have no approved programs yet, this gate blocks commercial links entirely rather than trusting a future editor to remember that.

    G-3: no banned expressions. A pattern list: income promises, absolutes, manufactured urgency. More on how badly this one behaved in a moment.

    G-4: not a near-duplicate of anything already published. Sequence similarity against the live corpus, pulled from the CMS at check time rather than from a local index that drifts.

    G-5: commercial relationships are disclosed above the fold. Only fires when G-2 found a commercial link, and then it requires the disclosure inside the first 400 characters, not in a footer.

    G-6: editorial responsibility and disclaimer are both present. Who stands behind this, and what it is not.

    G-7: no generation artifacts. Stray model chatter that survived into the draft.

    G-8: dates are sane. A surprisingly common failure: an article published in 2026 that confidently discusses “this year’s” pricing from 2024.

    Terminal output of the publication gate run for this article, showing all eight checks passing and the post being published as post_id 70.
    The gate run that published this article. A single failure writes the post as a draft instead; there is no flag to skip a check.

    What the first run found

    Six of seven live articles failed, and the failures were not subtle.

    One article carried an income figure in its own title, a specific monthly yen amount presented as an outcome. It had been sitting on the front page for weeks. Nobody had decided to publish that claim; a draft had simply never been argued with.

    Three articles were near-duplicates of each other. Same topic, same structure, marginally different phrasing, all three indexed and competing with each other for the same query. That is the exact pattern the scaled-content guidance describes, and we had produced it without noticing, because each one looked fine on the day it was written.

    Seven of seven were missing any link to our own disclosure and editorial pages. Those pages had existed since June. Not one article pointed at them. Every individual article had been reviewed by a person; the property as a whole had been reviewed by nobody.

    Separately, and outside the gates, we found the sitemap had been frozen since June 9 and was serving eleven URLs that no longer existed.

    None of this required sophistication to find. It required something that looks at every article the same way every time, which is precisely the thing a human reviewer stops doing around article four.

    The gates were wrong before they were right

    The first version of G-3 was close to useless, and this is the part most write-ups skip.

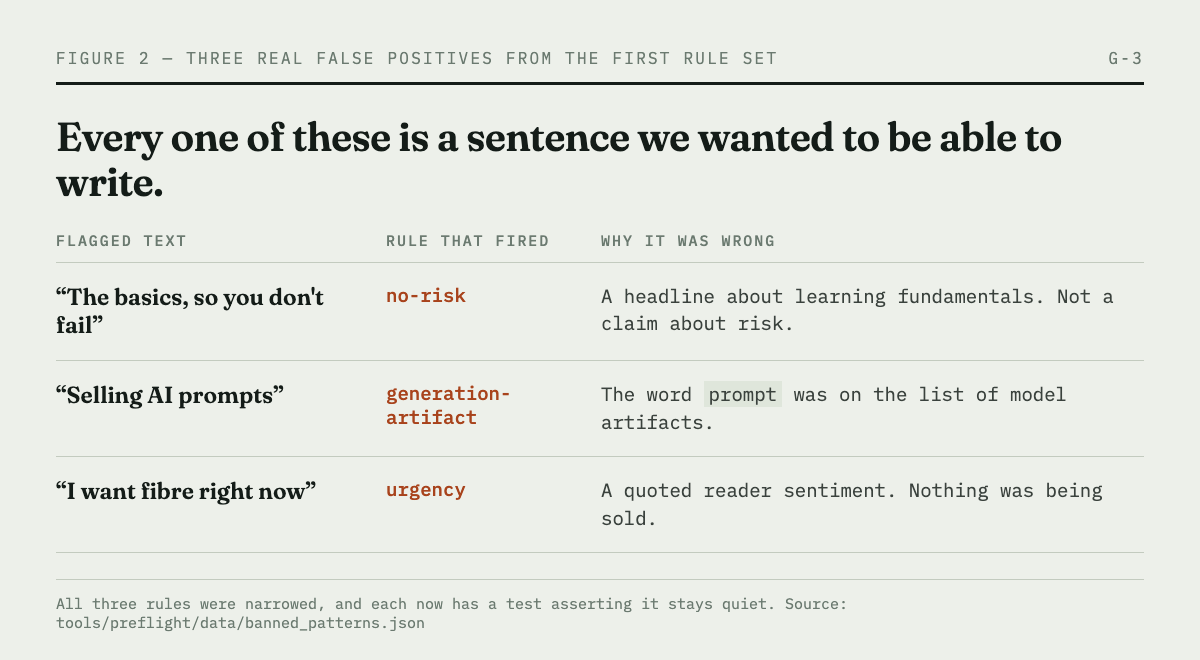
    It flagged a Japanese headline meaning roughly “the fundamentals, so you don’t fail” as a no-risk claim. It is not a claim about risk; it is an ordinary way to title an explainer. It flagged an article about selling AI prompts because the word “prompt” appeared in our list of generation artifacts. It flagged the phrase “right now” in a sentence where nothing was being sold.

    On the English side the pattern list had the same disease in a different accent. Early drafts of the rules would have flagged a sentence stating there is real risk in unattended automation, because it contained the word risk near a negation. They would have flagged “the server costs twelve dollars a month” as a price claim and “the site earned zero” as an income claim. Those are the sentences we most want to be able to write.

    Table of three real false positives from the first rule set: a headline about fundamentals flagged as a no-risk claim, an article about selling AI prompts flagged as a model artifact, and a quoted reader sentiment flagged as urgency.
    Three real false positives from the first rule set. Every one of them is a sentence we wanted to be able to write.

    So we narrowed the rules and wrote tests that assert non-detection. Fifty tests now, and a meaningful share of them exist to prove the checker stays quiet on honest sentences. The fixtures are real headlines from our own deleted drafts, not invented examples.

    This matters more than the detections do. A checker with a high false-positive rate does not get tuned. It gets bypassed, and then it is worse than nothing, because the bypass becomes the habit and the green checkmark becomes a lie.

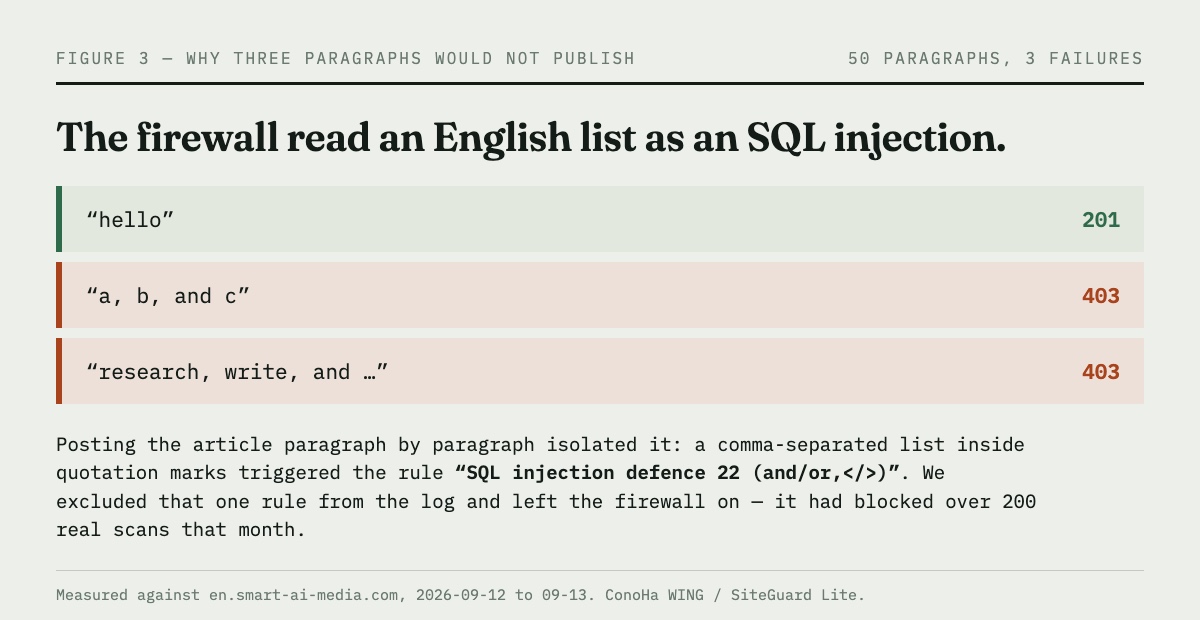
    Three test strings posted to the site: a plain greeting returns 201, while a comma-separated list inside quotation marks returns 403, blocked by an SQL injection firewall rule.
    A separate failure, found the same week: the host firewall read an ordinary English list as an SQL injection and refused three paragraphs of this article. Bisecting the post paragraph by paragraph isolated it. The full account of that week is here.

    What it does not do

    The gates cannot tell you whether an article is worth reading. They cannot detect a confident factual error, an outdated recommendation, or a comparison that quietly favors the advertiser paying the most. Every one of those still requires a person who knows the subject.

    What the gates do is clear the floor, so that the human review is spent on judgment instead of on checking whether the links work. That is the whole argument. Automated checks are not a substitute for editorial oversight; they are what makes the scarce oversight land somewhere useful. We learned how narrow that floor really is a few days later, when all eight gates passed three articles that reached readers as raw markup.

    If you want to build one

    You do not need a framework. Ours is a few hundred lines of Python using only the standard library, and it runs in under a minute against the live CMS.

    Start with the failure you have already had. If you have shipped a dead link, write G-1 first. Run it against your existing published articles before you write another word, because the archive is where the evidence is, and it will tell you which gates you actually need.

    Then make it fail closed, and resist the urge to add an override flag. The moment there is a documented way to skip the gates under deadline pressure, the gates describe your intentions rather than your output.

    We are about seven weeks into this and the checker has caught things a human review already passed, more than once. That is not an argument that the humans were careless. It is an argument that reading an article and auditing an article are different tasks, and only one of them gets harder the more articles you have.


    Editorial note. Written and edited by the operator of this site. Every figure here comes from our own systems and is reproducible from our logs. Where we describe a failure, we found it on our own property, not someone else’s.

    Disclosure. This article contains no affiliate or sponsored links. This site may earn commissions from links in other articles, and those articles carry their own disclosure at the top. Nothing here is professional advice.
  • We ran a business on seven AI agents for three months. Every failure had the same root cause.

    We ran a business on seven AI agents for three months. Every failure had the same root cause.

    We gave seven scheduled AI agents real jobs inside a small media business. One wrote articles. One logged KPIs every night. One produced a weekly board report. They ran on cron. Nobody watched them closely.

    Three months later the business had published 21 drafts we could not use, served Google 11 dead URLs, and earned zero revenue.

    This is the incident log, with the numbers. If you are putting agents into an operational loop, the specific failures matter more than the general advice, so they are all here.

    Failure 1: the article factory produced the same article five times

    The writing agent ran every morning at 9:00 and published directly. For weeks nobody read the output. When we finally audited it:

    • One title — a fiber-internet comparison — appeared five times, published on five different days
    • A second title appeared three times
    • Several posts linked to affiliate programs we had never been approved for
    • One post claimed an earnings figure with no basis behind it
    • One post’s title was literally the model’s own error message asking the operator a clarifying question

    Of 21 drafts sitting in the queue, zero were usable.

    The pipeline itself never broke. It ran on schedule every single day. Only the output was broken — which is precisely why nobody noticed.

    Failure 2: the morning agents ran two hours late, every day

    Two agents were scheduled for 6:10 and 6:45. We measured when they actually executed: 8:18 and 8:20.

    The cause was mundane. The scheduler only fires while the host application is running, and the machine was not awake at 6:00. Every morning the jobs queued and executed whenever the app opened.

    One of those agents was supposed to prepare a 7:30 posting slot. It never once made it in time. That slot stayed empty for three weeks.

    The same cause corrupted our measurement. The nightly KPI logger was scheduled for 22:00 — an hour when the machine was reliably awake — and it mostly ran. But across a 20-day window we had 12 days of data. Forty percent missing, and no alert, because a job that never runs produces no error.

    The lesson we took: you can only schedule automation for hours when the host is reliably available. For us that was night, not morning. Check your actual execution timestamps against your intended schedule. They may not match.

    Failure 3: two agents wrote to the same output

    One agent generated social posts. Another scheduled them. Both had been given permission to publish to the same channel.

    Neither malfunctioned. Each did its job correctly. The result was 1.25× the intended daily volume and the same link going out twice in one day.

    We fixed it by making the output single-writer: one agent owns the channel, every other agent may only deposit material for it. That rule has held since.

    Failure 4: four weeks of publishing that search engines never saw

    This one cost us the most and we found it last.

    We published an article and watched for a month. No impressions. We assumed it was ranking slowly — new sites take time. Then we inspected the URL directly in Search Console:

    Last crawl: N/A
    Referring sitemaps: none detected
    Referring pages: none detected

    Google had never crawled it. Not ranked low — never fetched.

    Three things had gone wrong at once, and none of them were visible from the admin dashboard:

    1. The sitemap had frozen three months earlier. It still advertised pages we had deleted — 11 URLs returning 404 — and listed none of the new ones.
    2. The new article had zero internal links pointing at it. No sitemap entry, no inbound link, no path in.
    3. The URL used non-ASCII characters, so every share turned into a wall of percent-encoding.

    Index coverage at that point: 9 pages indexed, 20 not indexed. The largest single reason for exclusion was “Not found (404)” — the dead URLs our own sitemap was handing to the crawler.

    All four had the same root cause

    Nobody looked at the output for long enough.

    That is the uncomfortable part. Automation removes the work, and it quietly removes the checking along with it. “It ran” and “it ran correctly” are different claims, and only the first one is self-reporting. The second requires a human to look.

    Failure 1 needed someone to read one published article. Failure 2 needed someone to compare a timestamp. Failure 3 was visible on the channel itself. Failure 4 needed one URL inspection. None of them required expertise. All of them required attention that the automation had implicitly retired.

    What we changed

    Checkpoint long jobs. An agent told to “research, write, and generate an image” in one run would die partway and leave nothing. We now save a skeleton first and append to it. A failed run leaves partial work instead of none.

    One writer per output. Any shared destination is owned by exactly one agent. Others deposit inputs. This single rule eliminated an entire class of collision.

    Machine checks before publication. We wrote a gate that runs eight checks before anything goes live: every link resolves, affiliate links point only to approved programs, no unsupported earnings claims, no near-duplicate of existing posts, required disclosures present, no model artifacts in the text, and dates that are internally consistent. It fails closed — a failed check means the post becomes a draft, not a publication. We have since written up each of those eight checks in detail, including the ones that were wrong when we first wrote them.

    We ran that gate against our existing published posts as a test. Every one of them failed. Problems the authors had not noticed were still sitting live on the site.

    A human still reads it. This is the one we were most tempted to skip, and the one that matters most. A machine check catches broken links and duplicates. It cannot judge whether a piece is worth reading. Google’s 2026 guidance draws the line in the same place: the question is not whether AI drafted the content, but whether a knowledgeable person reviewed it. Sites publishing unreviewed AI output at volume have reported traffic losses of 50–80%.

    The gate’s job, we decided, is not to approve content. It is to make sure only things worth a human’s attention reach a human.

    The volume question

    One more data point, because it cuts against the instinct.

    On a separate property we increased published articles from 13 to 23 in a single push. In the days immediately after, followers went down, from 18 to 17. What moved the number later was not volume — it was fixing the profile and the navigation, and publishing one piece on a topic nobody else was covering.

    Our most-read piece across everything we shipped was not the highest-volume output. It was the one thing we knew that others did not.

    If you are about to do this

    Decide your review cadence before you decide your automation scope. We did it in the other order and paid for three months.

    Concretely, from our own logs:

    • Compare intended schedule against actual execution timestamps, once
    • Open your sitemap in a browser and confirm your most recent post is listed
    • Inspect one published URL and check the “last crawl” field
    • Read one full piece of output per week, start to finish

    The fourth item is the one we skipped, and it was the one that would have caught everything.

    We are running the same system again with those changes in place. We will publish what happens, including the parts that do not work.


    Editorial note: written and fact-checked against our own operational logs and analytics. All figures are measured from our own properties, not estimates. Reviewed before publication by the site operator.

    Disclosure: this article contains no affiliate links. Where we recommend tools in future articles, we will state clearly whether we have a commercial relationship with them.