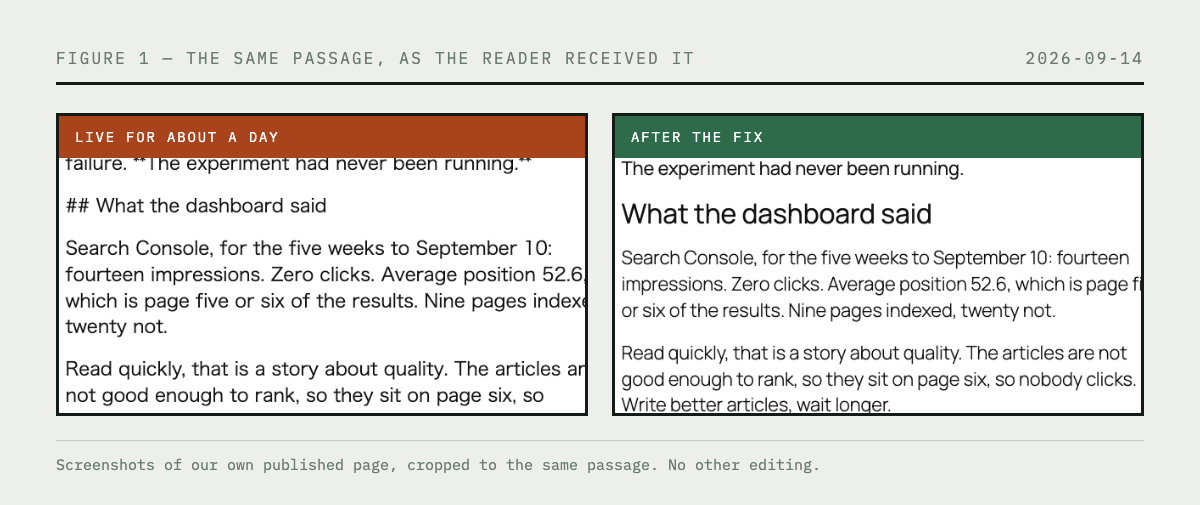
For about a day, three of the four articles on this site displayed their own markup. Headings arrived as ## What the dashboard said, with the hashes sitting in the text. Bold arrived wrapped in asterisks. Links arrived as square brackets followed by a naked URL in parentheses.
Every one of those articles had passed an eight-gate publication checker with no failures. The checker was working exactly as designed. That is the part worth writing down.
What the reader actually got
The left panel is a live article as published. The right is the same passage after the fix.
How it happened
Our publishing pipeline reads a file, runs the gates, then posts the body to the WordPress REST API. The articles were written in Markdown. WordPress does not render Markdown. It stores what you send it.
The assumption was sitting in our own source code, in a comment on the data model:
body: HTML or Markdown
Nobody had ever tested the second half of that sentence. The first article on this site happened to be written in raw HTML, so it rendered correctly. When we switched to writing in Markdown, everything after it broke, quietly, in a way that looked fine from every angle we were checking.
Why the checker did not catch it
This is the useful part. Here is what the eight gates ask:
Does every link resolve? Do commercial links point only to approved programmes? Are there banned expressions? Is this a near-duplicate of something already published? Is the disclosure above the fold? Are the editorial note and disclaimer present? Are there generation artifacts in the text? Are the dates internally consistent?
Read those eight as a set. Every single one is a question about what the article says. Not one of them is a question about whether the article has a form.
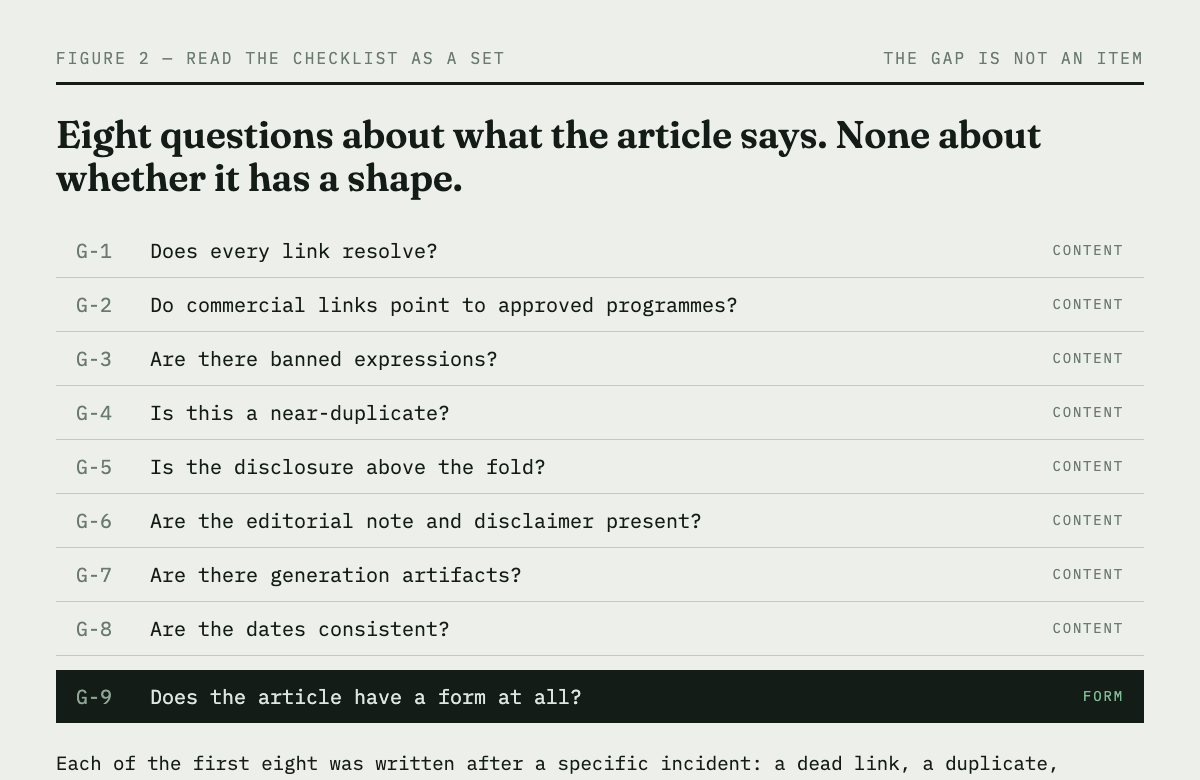
That was not an oversight in the sense of forgetting an item. Each gate was written in response to a specific failure we had already lived through: a dead link, a duplicate, an income claim in a headline. The list was a list of scars. You cannot write a scar for an injury you have not had yet, which is precisely why a checklist built from experience has a predictable shape: it is dense where you have been hurt and empty everywhere else.
The gap was not in the list. It was in the space the list did not cover.
Why a human did not catch it either
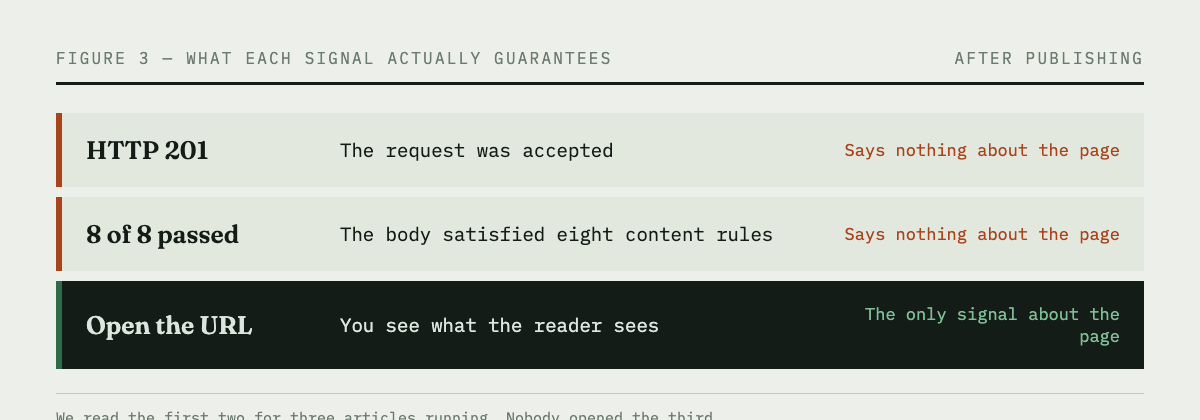
We publish, then read the result of the publish. The API returned 201. The gate report printed eight passes. A person read both of those and moved on.
Both of those signals were true. Both of them were about the system. Neither of them was about the page.
Nobody opened the public URL. Not once, across three articles. The information was one click away for a day and a half, sitting in a browser tab nobody opened, because the dashboard had already said the thing was fine.
This is the same failure we wrote about two weeks ago, where a site produced no revenue for fifteen months while the instrument measuring it was disconnected. Same shape. We read the report instead of the thing the report described. Knowing about the pattern in the abstract did nothing to stop us repeating it eleven days later.
What we changed
A converter, so the input is always valid output. Markdown now becomes HTML before it reaches the API. A few hundred lines, standard library only, handling exactly the notation our articles actually use and nothing else.
A ninth gate that fails closed. G-9 scans the body that is about to be posted for surviving markup notation. If it finds any, nothing publishes. Writing the gate took twenty minutes. It exists now because the failure happened, which is the same way the other eight got here.
A second checker, at a different scale. The nine gates all look inside one article. We later built a set of checks for the space between articles, which is where our worst failures had been living.
A rule that is not automated at all. After publishing, open the public URL and look at the page. Not the API response. Not the gate report. The page, as a reader loads it.
That last one is the only part of this that generalises. The first two fix this specific bug. A machine check can confirm that a page contains no leftover asterisks. It cannot tell you that a paragraph is confusing, that a figure landed in the wrong place, or that the article now opens with two identical headlines because the cover image repeats the title. Every one of those was also true of our pages this week, and the only thing that found them was a person looking at the page.
If you publish through an API
Three things, in order of how much time they save.
Load the public URL after every publish. The response code tells you the request succeeded. It tells you nothing about what the reader gets.
Assume every comment in your own code is untested. The word or in a code comment is where bugs live. Ours said Markdown would work. It had never worked. It had simply never been tried, and the comment made it look like a decision rather than an assumption.
When you add a check, ask what category it belongs to. Our eight gates were all one category. That is invisible while you are adding them one at a time in response to incidents, and obvious the moment you write them out as a list and read them together. If every check you have asks the same kind of question, you have a blind spot the exact size of the questions you are not asking.
None of this made the articles better. It made them legible, which is the floor rather than the ceiling. But a reader who sees asterisks in the second paragraph does not reach the argument, so the floor is where the work has to start.
Editorial note. Written and edited by the operator of this site. The screenshots are of our own pages, taken before and after the fix on 2026-09-14. The affected articles were live in the broken state for roughly one day.
Disclosure. This article contains no affiliate or sponsored links. This site may earn commissions from links in other articles, and those articles carry their own disclosure at the top. Nothing here is professional advice.